 |
Q.ANT Native Computing Toolkit 2.4.0
All you need for photonic computing
|
|
Q.ANT Native Computing Toolkit 2.4.0
All you need for photonic computing
|
#include <stdbool.h>#include <stddef.h>#include <stdint.h>#include <dlpack/dlpack.h>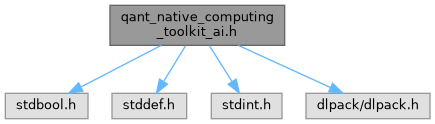
Go to the source code of this file.
Typedefs | |
| typedef struct ConvWeightsHandle | ConvWeightsHandle |
| Opaque handle to convolution weights that have been uploaded to device memory. | |
| typedef struct ConvTransposeWeightsHandle | ConvTransposeWeightsHandle |
| Opaque handle to transposed convolution weights that have been uploaded to device memory. | |
Functions | |
| DLManagedTensorVersioned * | add_bias_fprop (const uint32_t npu_id, DLManagedTensorVersioned const *features, DLManagedTensorVersioned const *bias) |
| Element-wise addition. Supports batched input. | |
| DLManagedTensorVersioned * | add_bias_for_conv2d_fprop (const uint32_t npu_id, DLManagedTensorVersioned const *features, DLManagedTensorVersioned const *bias) |
| Element-wise addition. Specifically used for conv2d. | |
| DLManagedTensorVersioned * | relu_fprop (const uint32_t npu_id, DLManagedTensorVersioned const *features) |
| Performs a forward pass through a ReLU layer. | |
| DLManagedTensorVersioned * | sigmoid_fprop (const uint32_t npu_id, DLManagedTensorVersioned const *features) |
| Performs a forward pass through a Sigmoid layer. | |
| DLManagedTensorVersioned * | softmax_fprop (const uint32_t npu_id, DLManagedTensorVersioned const *features) |
| Performs a forward pass through a Softmax layer. | |
| DLManagedTensorVersioned * | conv_fprop (const uint32_t npu_id, DLManagedTensorVersioned const *features, DLManagedTensorVersioned const *weights, size_t const padding, size_t const stride, size_t const dilation) |
| Performs a forward pass through a convolution layer. | |
| DLManagedTensorVersioned * | conv_transpose_fprop (const uint32_t npu_id, DLManagedTensorVersioned const *features, DLManagedTensorVersioned const *weights, size_t const padding, size_t const stride, size_t const dilation, size_t const output_padding) |
| Performs a forward pass through a transposed convolution layer. | |
| ConvWeightsHandle * | upload_conv_weights (const uint32_t npu_id, DLManagedTensorVersioned const *weights) |
| Uploads convolution weights to device memory so they can be reused across multiple calls to conv_fprop_preloaded_weights(). | |
| int | conv_weights_free (ConvWeightsHandle *handle) |
| Frees convolution weights previously uploaded with upload_conv_weights(). | |
| DLManagedTensorVersioned * | conv_fprop_preloaded_weights (DLManagedTensorVersioned const *features, ConvWeightsHandle const *weights, size_t const padding, size_t const stride, size_t const dilation) |
| Performs a forward pass through a convolution layer using weights already uploaded to device memory. The computation runs on the NPU that holds the weights. | |
| ConvTransposeWeightsHandle * | upload_conv_transpose_weights (const uint32_t npu_id, DLManagedTensorVersioned const *weights) |
| Uploads transposed convolution weights to device memory so they can be reused across multiple calls to conv_transpose_fprop_preloaded_weights(). | |
| int | conv_transpose_weights_free (ConvTransposeWeightsHandle *handle) |
| Frees transposed convolution weights previously uploaded with upload_conv_transpose_weights(). | |
| DLManagedTensorVersioned * | conv_transpose_fprop_preloaded_weights (DLManagedTensorVersioned const *features, ConvTransposeWeightsHandle const *weights, size_t const padding, size_t const stride, size_t const dilation, size_t const output_padding) |
| Performs a forward pass through a transposed convolution layer using weights already uploaded to device memory. The computation runs on the NPU that holds the weights. | |
| DLManagedTensorVersioned * | batchnorm2d_fprop (const uint32_t npu_id, DLManagedTensorVersioned const *features, DLManagedTensorVersioned const *means, DLManagedTensorVersioned const *variances, DLManagedTensorVersioned const *weights, DLManagedTensorVersioned const *bias, float const eps) |
| Performs a forward pass through a batchnorm2d layer. | |
| DLManagedTensorVersioned * | maxpool2d_fprop (const uint32_t npu_id, DLManagedTensorVersioned const *features, size_t const kernel_height, size_t const kernel_width, size_t const padding, size_t const stride) |
| Performs a forward pass through a maxpooling2d layer. | |
| DLManagedTensorVersioned * | avgpool2d_fprop (const uint32_t npu_id, DLManagedTensorVersioned const *features, size_t const kernel_height, size_t const kernel_width, size_t const padding, size_t const stride, bool const count_include_pad) |
| Performs a forward pass through a avgpooling2d layer. | |
| DLManagedTensorVersioned * | adaptive_maxpool2d_fprop (const uint32_t npu_id, DLManagedTensorVersioned const *features, size_t const output_height, size_t const output_width) |
| Performs a forward pass through an adaptive maxpooling2d layer. | |
| DLManagedTensorVersioned * | adaptive_avgpool2d_fprop (const uint32_t npu_id, DLManagedTensorVersioned const *features, size_t const output_height, size_t const output_width) |
| Performs a forward pass through an adaptive avgpooling2d layer. | |
| DLManagedTensorVersioned * | calc_kan_layer_fprop (const uint32_t npu_id, DLManagedTensorVersioned const *features, DLManagedTensorVersioned const *phis, DLManagedTensorVersioned const *ampls, DLManagedTensorVersioned const *ks) |
| Calculates a Q.ANT version of a KAN layer (https://arxiv.org/abs/2404.19756) based on scaled_periodic_nl. | |
| typedef struct ConvTransposeWeightsHandle ConvTransposeWeightsHandle |
Opaque handle to transposed convolution weights that have been uploaded to device memory.
Instances are created by upload_conv_transpose_weights() and must be released exactly once with conv_transpose_weights_free(). Using a handle after it has been freed is undefined behavior.
| typedef struct ConvWeightsHandle ConvWeightsHandle |
Opaque handle to convolution weights that have been uploaded to device memory.
Instances are created by upload_conv_weights() and must be released exactly once with conv_weights_free(). Using a handle after it has been freed is undefined behavior.
| DLManagedTensorVersioned * adaptive_avgpool2d_fprop | ( | const uint32_t | npu_id, |
| DLManagedTensorVersioned const * | features, | ||
| size_t const | output_height, | ||
| size_t const | output_width ) |
Performs a forward pass through an adaptive avgpooling2d layer.
Only works for symmetric input and output sizes. Input size has to be integer multiple of output size.
| npu_id | The identifier of the NPU on which to perform the operation. |
| features | A 4D tensor with data type bfloat16 and shape (n_batches, n_channels, height, width) |
| output_height | Height of the output. |
| output_width | Width of the output. |
| DLManagedTensorVersioned * adaptive_maxpool2d_fprop | ( | const uint32_t | npu_id, |
| DLManagedTensorVersioned const * | features, | ||
| size_t const | output_height, | ||
| size_t const | output_width ) |
Performs a forward pass through an adaptive maxpooling2d layer.
Only works for symmetric input and output sizes. Input size has to be integer multiple of output size.
| npu_id | The identifier of the NPU on which to perform the operation. |
| features | A 4D tensor with data type bfloat16 and shape (n_batches, n_channels, height, width) |
| output_height | Height of the output. |
| output_width | Width of the output. |
| DLManagedTensorVersioned * add_bias_for_conv2d_fprop | ( | const uint32_t | npu_id, |
| DLManagedTensorVersioned const * | features, | ||
| DLManagedTensorVersioned const * | bias ) |
Element-wise addition. Specifically used for conv2d.
| npu_id | The identifier of the NPU on which to perform the operation. |
| features | A 4D tensor with data type bfloat16 and shape (n_batches, n_channels, height, width) |
| bias | A 1D tensor with data type bfloat16 and shape (n_channels) |
| DLManagedTensorVersioned * add_bias_fprop | ( | const uint32_t | npu_id, |
| DLManagedTensorVersioned const * | features, | ||
| DLManagedTensorVersioned const * | bias ) |
Element-wise addition. Supports batched input.
| npu_id | The identifier of the NPU on which to perform the operation. |
| features | A 2D tensor with data type bfloat16 and shape (n_batches, n_channels). |
| bias | A 1D tensor with data type bfloat16 and shape (n_channels) |
| DLManagedTensorVersioned * avgpool2d_fprop | ( | const uint32_t | npu_id, |
| DLManagedTensorVersioned const * | features, | ||
| size_t const | kernel_height, | ||
| size_t const | kernel_width, | ||
| size_t const | padding, | ||
| size_t const | stride, | ||
| bool const | count_include_pad ) |
Performs a forward pass through a avgpooling2d layer.
For a mathematical definition, see https://en.wikipedia.org/wiki/Pooling_layer
| npu_id | The identifier of the NPU on which to perform the operation. |
| features | A 4D tensor with data type bfloat16 and shape (n_batches, n_channels, height, width) |
| kernel_height | Height of the pooling kernel. |
| kernel_width | Width of the pooling kernel. |
| padding | Amount of padding added to the input features. |
| stride | Step size for moving the kernel over the input features. |
| count_include_pad | When True, will include the zero-padding in the averaging calculation. |
| DLManagedTensorVersioned * batchnorm2d_fprop | ( | const uint32_t | npu_id, |
| DLManagedTensorVersioned const * | features, | ||
| DLManagedTensorVersioned const * | means, | ||
| DLManagedTensorVersioned const * | variances, | ||
| DLManagedTensorVersioned const * | weights, | ||
| DLManagedTensorVersioned const * | bias, | ||
| float const | eps ) |
Performs a forward pass through a batchnorm2d layer.
For a mathematical definition, see https://en.wikipedia.org/wiki/Batch_normalization
| npu_id | The identifier of the NPU on which to perform the operation. |
| features | A 4D tensor with data type bfloat16 and shape (n_batches, n_channels, height, width) |
| means | A 1D tensor containing the mean values for each feature, with data type bfloat16 and length n_channels |
| variances | A 1D tensor containing the variance values for each feature, with data type bfloat16 and length n_channels |
| weights | A 1D tensor containing the parameter for each feature, with data type bfloat16 and length n_channels |
| bias | A 1D tensor containing the bias value for each feature, with data type bfloat16 and length n_channels |
| eps | A small value added to the variance for numerical stability. |
| DLManagedTensorVersioned * calc_kan_layer_fprop | ( | const uint32_t | npu_id, |
| DLManagedTensorVersioned const * | features, | ||
| DLManagedTensorVersioned const * | phis, | ||
| DLManagedTensorVersioned const * | ampls, | ||
| DLManagedTensorVersioned const * | ks ) |
Calculates a Q.ANT version of a KAN layer (https://arxiv.org/abs/2404.19756) based on scaled_periodic_nl.
The mathematical function is
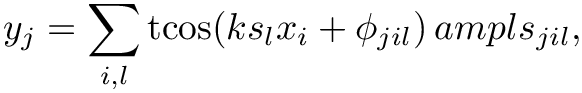
where  is the input (vector),
 is the frequency components,
 the phase offsets (tensor) and
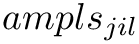 the amplitude (tensor) and
 output (vector).
 denotes the cosine-related shape of the periodic optical nonlinearity.
| npu_id | The identifier of the NPU on which to perform the operation. |
| features | A 2D input tensor with shape (n_batches, n_channels_in), with data type bfloat16. |
| phis | A 3D tensor of phase offsets, shape (n_channels_out, n_channels_in, n_ks), with data type bfloat16. |
| ampls | A 3D array of amplitudes, same shape as phis, with data type bfloat16. |
| ks | A 1D tensor of frequency components, shape (n_ks), with data type bfloat16. |
| DLManagedTensorVersioned * conv_fprop | ( | const uint32_t | npu_id, |
| DLManagedTensorVersioned const * | features, | ||
| DLManagedTensorVersioned const * | weights, | ||
| size_t const | padding, | ||
| size_t const | stride, | ||
| size_t const | dilation ) |
Performs a forward pass through a convolution layer.
| npu_id | The identifier of the NPU on which to perform the operation. |
| features | A 4D tensor with data type bfloat16 and shape (n_batches, in_channels, height, width) |
| weights | A 4D tensor with data type bfloat16 and shape (out_channels, in_channels, height, width) |
| padding | Amount of padding added to the input features. |
| stride | Step size for moving the kernel over the input features. |
| dilation | Dilation ("zoom out") of the kernel. |
| DLManagedTensorVersioned * conv_fprop_preloaded_weights | ( | DLManagedTensorVersioned const * | features, |
| ConvWeightsHandle const * | weights, | ||
| size_t const | padding, | ||
| size_t const | stride, | ||
| size_t const | dilation ) |
Performs a forward pass through a convolution layer using weights already uploaded to device memory. The computation runs on the NPU that holds the weights.
| features | A 4D tensor with data type bfloat16 and shape (n_batches, in_channels, height, width) |
| weights | Handle to the weights, as returned by upload_conv_weights(). |
| padding | Amount of padding added to the input features. |
| stride | Step size for moving the kernel over the input features. |
| dilation | Dilation ("zoom out") of the kernel. |
| DLManagedTensorVersioned * conv_transpose_fprop | ( | const uint32_t | npu_id, |
| DLManagedTensorVersioned const * | features, | ||
| DLManagedTensorVersioned const * | weights, | ||
| size_t const | padding, | ||
| size_t const | stride, | ||
| size_t const | dilation, | ||
| size_t const | output_padding ) |
Performs a forward pass through a transposed convolution layer.
| npu_id | The identifier of the NPU on which to perform the operation. |
| features | A 4D tensor with data type bfloat16 and shape (n_batches, in_channels, height, width) |
| weights | A 4D tensor with data type bfloat16 and shape (in_channels, out_channels, height, width) |
| padding | Amount of padding added to the input features. |
| stride | Step size for moving the kernel over the input features. |
| dilation | Dilation ("zoom out") of the kernel. |
| output_padding | Padding for the returned features. |
| DLManagedTensorVersioned * conv_transpose_fprop_preloaded_weights | ( | DLManagedTensorVersioned const * | features, |
| ConvTransposeWeightsHandle const * | weights, | ||
| size_t const | padding, | ||
| size_t const | stride, | ||
| size_t const | dilation, | ||
| size_t const | output_padding ) |
Performs a forward pass through a transposed convolution layer using weights already uploaded to device memory. The computation runs on the NPU that holds the weights.
| features | A 4D tensor with data type bfloat16 and shape (n_batches, in_channels, height, width) |
| weights | Handle to the weights, as returned by upload_conv_transpose_weights(). |
| padding | Amount of padding added to the input features. |
| stride | Step size for moving the kernel over the input features. |
| dilation | Dilation ("zoom out") of the kernel. |
| output_padding | Padding for the returned features. |
| int conv_transpose_weights_free | ( | ConvTransposeWeightsHandle * | handle | ) |
Frees transposed convolution weights previously uploaded with upload_conv_transpose_weights().
| handle | The handle to free. Must not be used afterwards. |
| int conv_weights_free | ( | ConvWeightsHandle * | handle | ) |
Frees convolution weights previously uploaded with upload_conv_weights().
| handle | The handle to free. Must not be used afterwards. |
| DLManagedTensorVersioned * maxpool2d_fprop | ( | const uint32_t | npu_id, |
| DLManagedTensorVersioned const * | features, | ||
| size_t const | kernel_height, | ||
| size_t const | kernel_width, | ||
| size_t const | padding, | ||
| size_t const | stride ) |
Performs a forward pass through a maxpooling2d layer.
For a mathematical definition, see https://en.wikipedia.org/wiki/Pooling_layer
| npu_id | The identifier of the NPU on which to perform the operation. |
| features | A 4D tensor with data type bfloat16 and shape (n_batches, n_channels, height, width) |
| kernel_height | Height of the pooling kernel. |
| kernel_width | Width of the pooling kernel. |
| padding | Amount of padding added to the input features. |
| stride | Step size for moving the kernel over the input features. |
| DLManagedTensorVersioned * relu_fprop | ( | const uint32_t | npu_id, |
| DLManagedTensorVersioned const * | features ) |
Performs a forward pass through a ReLU layer.
For a mathematical definition, see https://en.wikipedia.org/wiki/Rectifier_(neural_networks)
| npu_id | The identifier of the NPU on which to perform the operation. |
| features | A 1D tensor with data type bfloat16. |
| DLManagedTensorVersioned * sigmoid_fprop | ( | const uint32_t | npu_id, |
| DLManagedTensorVersioned const * | features ) |
Performs a forward pass through a Sigmoid layer.
For a mathematical definition, see https://en.wikipedia.org/wiki/Sigmoid_function
| npu_id | The identifier of the NPU on which to perform the operation. |
| features | A 1D tensor with data type bfloat16. |
| DLManagedTensorVersioned * softmax_fprop | ( | const uint32_t | npu_id, |
| DLManagedTensorVersioned const * | features ) |
Performs a forward pass through a Softmax layer.
For a mathematical definition, see https://en.wikipedia.org/wiki/Softmax_function
| npu_id | The identifier of the NPU on which to perform the operation. |
| features | A 2D tensor with data type bfloat16 and shape (1, N). |
| ConvTransposeWeightsHandle * upload_conv_transpose_weights | ( | const uint32_t | npu_id, |
| DLManagedTensorVersioned const * | weights ) |
Uploads transposed convolution weights to device memory so they can be reused across multiple calls to conv_transpose_fprop_preloaded_weights().
| npu_id | The identifier of the NPU on which the weights are stored. |
| weights | A 4D tensor with data type bfloat16 and shape (in_channels, out_channels, height, width) |
| ConvWeightsHandle * upload_conv_weights | ( | const uint32_t | npu_id, |
| DLManagedTensorVersioned const * | weights ) |
Uploads convolution weights to device memory so they can be reused across multiple calls to conv_fprop_preloaded_weights().
| npu_id | The identifier of the NPU on which the weights are stored. |
| weights | A 4D tensor with data type bfloat16 and shape (out_channels, in_channels, height, width) |
 1.17.0