 |
Q.ANT Native Computing Toolkit 2.4.0
All you need for photonic computing
|
|
Q.ANT Native Computing Toolkit 2.4.0
All you need for photonic computing
|
Native math functionality. More...
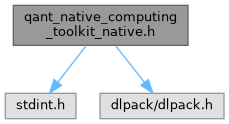
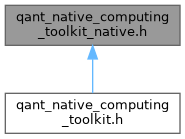
Go to the source code of this file.
Functions | |
| DLManagedTensorVersioned * | mul_npu (const uint32_t npu_id, DLManagedTensorVersioned const *us, DLManagedTensorVersioned const *vs) |
| Multiplies two 1D Tensors element-wise. | |
| DLManagedTensorVersioned * | calc_scaled_periodic_nl_fprop (const uint32_t npu_id, DLManagedTensorVersioned const *features, DLManagedTensorVersioned const *weights) |
Calculates a scaled periodic nonlinearity pairwise for all elements of features  and weights  . | |
| DLManagedTensorVersioned * | linear_fprop (const uint32_t npu_id, DLManagedTensorVersioned const *features, DLManagedTensorVersioned const *weights) |
| Performs a linear forward propagation between input features and a weight matrix. | |
| DLManagedTensorVersioned * | linear_fprop_preloaded_weights (DLManagedTensorVersioned const *features, QantMemoryHandle const *weights) |
| Same as linear_fprop(), but uses a weight matrix previously uploaded. | |
| int | linear_fprop_preloaded (QantMemoryHandle const *features, QantMemoryHandle const *weights, QantMemoryHandle const *result) |
| Same as linear_fprop(), but features, weights and result all live in device memory. | |
Native math functionality.
Functionality that is available directly on the NPU with no data processing on the host.
| DLManagedTensorVersioned * calc_scaled_periodic_nl_fprop | ( | const uint32_t | npu_id, |
| DLManagedTensorVersioned const * | features, | ||
| DLManagedTensorVersioned const * | weights ) |
Calculates a scaled periodic nonlinearity pairwise for all elements of features and weights .
The output for each input pair is 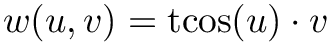 , where
 is a
 - periodic function with values between
 and
 , similar to a cosine.
| npu_id | The identifier of the NPU on which to perform the operation. |
| features | A 1D tensor with data type bfloat16. |
| weights | A 1D tensor with data type bfloat16, same length as features. |
| DLManagedTensorVersioned * linear_fprop | ( | const uint32_t | npu_id, |
| DLManagedTensorVersioned const * | features, | ||
| DLManagedTensorVersioned const * | weights ) |
Performs a linear forward propagation between input features and a weight matrix.
The operation computes output = features @ weights^T, i.e.:
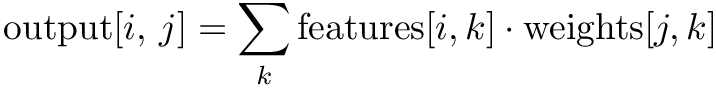
Note that this is not a plain features @ weights — the weight matrix is implicitly transposed, matching the convention where weights has shape (n_channels_out, n_channels_in).
| npu_id | The identifier of the NPU on which to perform the operation. |
| features | A 2D tensor with data type bfloat16 and shape (n_batches, n_channels_in). |
| weights | A 2D tensor with data type bfloat16 and shape (n_channels_out, n_channels_in). |
| int linear_fprop_preloaded | ( | QantMemoryHandle const * | features, |
| QantMemoryHandle const * | weights, | ||
| QantMemoryHandle const * | result ) |
Same as linear_fprop(), but features, weights and result all live in device memory.
The features and weights must have been uploaded with npu_upload() or npu_upload_into() (data roles Features and Weights respectively). The result handle is not allocated by this function: it must be allocated beforehand, e.g. with npu_allocate(), on the same NPU and with data role Features. The operation is performed on the NPU the weights were uploaded to.
| features | Handle to the features with shape (n_batches, n_channels_in). |
| weights | Handle to the weights with shape (n_channels_out, n_channels_in). |
| result | Pre-allocated handle to receive the result with shape (n_batches, n_channels_out) and data role Features. Its previous contents are overwritten. |
| DLManagedTensorVersioned * linear_fprop_preloaded_weights | ( | DLManagedTensorVersioned const * | features, |
| QantMemoryHandle const * | weights ) |
Same as linear_fprop(), but uses a weight matrix previously uploaded.
Use in combination with npu_upload() or npu_upload_into() (data role Weights). The operation is performed on the NPU the weights were uploaded to.
| features | A 2D tensor with data type bfloat16 and shape (n_batches, n_channels_in). |
| weights | Handle to the weights with shape (n_channels_out, n_channels_in), as returned by npu_upload(). |
| DLManagedTensorVersioned * mul_npu | ( | const uint32_t | npu_id, |
| DLManagedTensorVersioned const * | us, | ||
| DLManagedTensorVersioned const * | vs ) |
Multiplies two 1D Tensors element-wise.
| npu_id | The identifier of the NPU on which to perform the operation. |
| us | The first input tensor. Must be data type bfloat16, same length as vs. |
| vs | The second input tensor. Must be data type bfloat16, same length as us. |
 1.17.0